Data centers designed for 130 kW racks, not retrofitted for them
Every GREENAIBOX facility was built from the slab up for liquid-cooled GPU systems, sited next to renewable generation and connected by a private backbone. Here is what sits underneath your cluster.
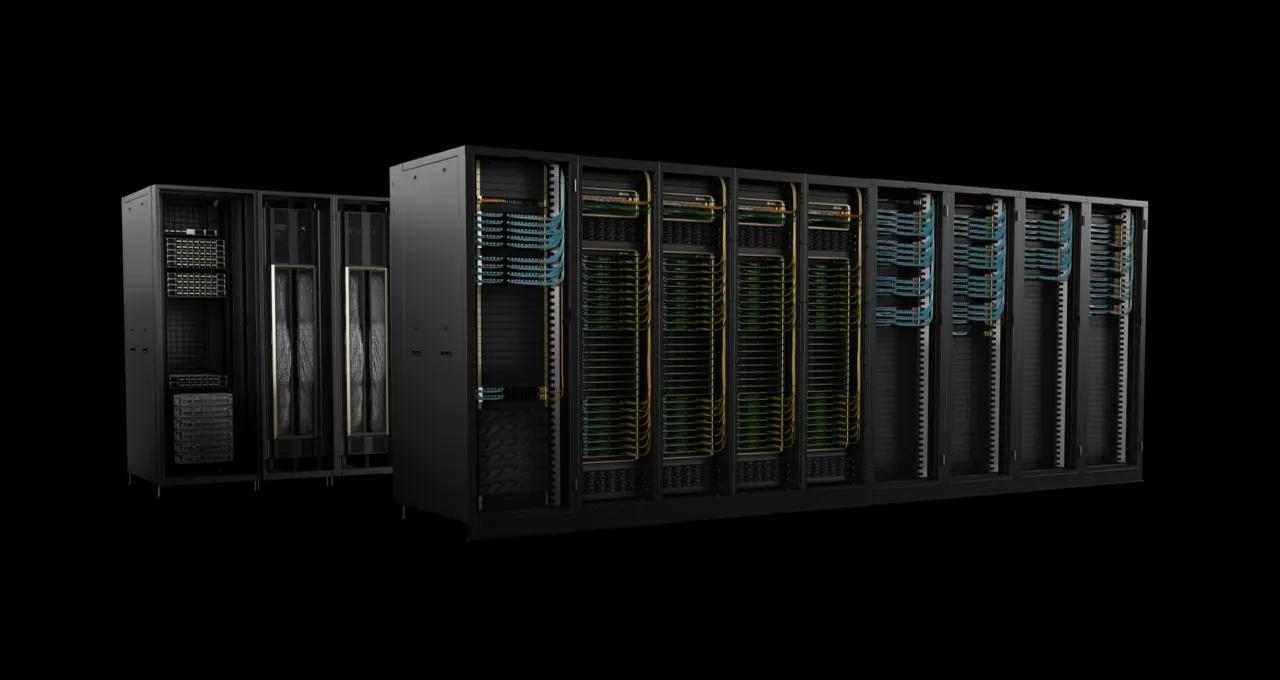 Data hall Image: NVIDIA
Where your GPUs live
Three live regions on two continents, each colocated with its power source. Choose by latency, data residency or hardware generation.
Columbia Basin, Washington
- Power sourceHydroelectric
- Capacity60 MW
- GPUsB200, H200, H100, L40S
- Latency5 ms to Seattle, 20 ms to San Francisco
Quebec, Canada
- Power sourceHydroelectric
- Capacity40 MW
- GPUsB200, H200, H100, A100
- Latency9 ms to Montreal, 18 ms to New York
Northern Sweden
- Power sourceHydro and wind
- Capacity30 MW
- GPUsB200, H100, GH200
- Latency12 ms to Stockholm, 30 ms to Frankfurt
Texas Panhandle
- Power sourceWind and solar with storage
- Capacity100 MW planned
- GPUsB300, GB300 NVL72
- Latency7 ms to Dallas
Built for the next three GPU generations
Liquid cooling everywhere
Direct-to-chip cold plates on every GPU, CPU and NVSwitch, with facility water loops at 32 to 40 C. Rear-door heat exchangers handle the remainder. No chillers most of the year.
Power you can plan around
Dual utility feeds, 2N distribution to the rack, UPS with 15 minutes of ride-through and generators with 72 hours of fuel. Long-term PPAs fix the price of energy for the life of your contract.
Physical security
Perimeter fencing, mantraps, biometric access, 24/7 staffed security and CCTV with 90-day retention. Private cages for custom cluster customers with their own access lists.
Non-blocking fabrics
NVIDIA Quantum-2 and Quantum-X800 InfiniBand in rail-optimized fat trees, sized so any cluster of up to 4,096 GPUs is non-blocking end to end.
Private backbone and peering
Diverse private wavelengths between regions, 100 Gb/s+ peering at major exchanges, and dedicated interconnects to AWS, Azure, Google Cloud and your own sites.
Operations that notice first
Every GPU, link, pump and breaker is instrumented. Anomaly detection flags a degrading HBM stack or a fabric link before it fails a job.
Halls built around the rack, not the other way round
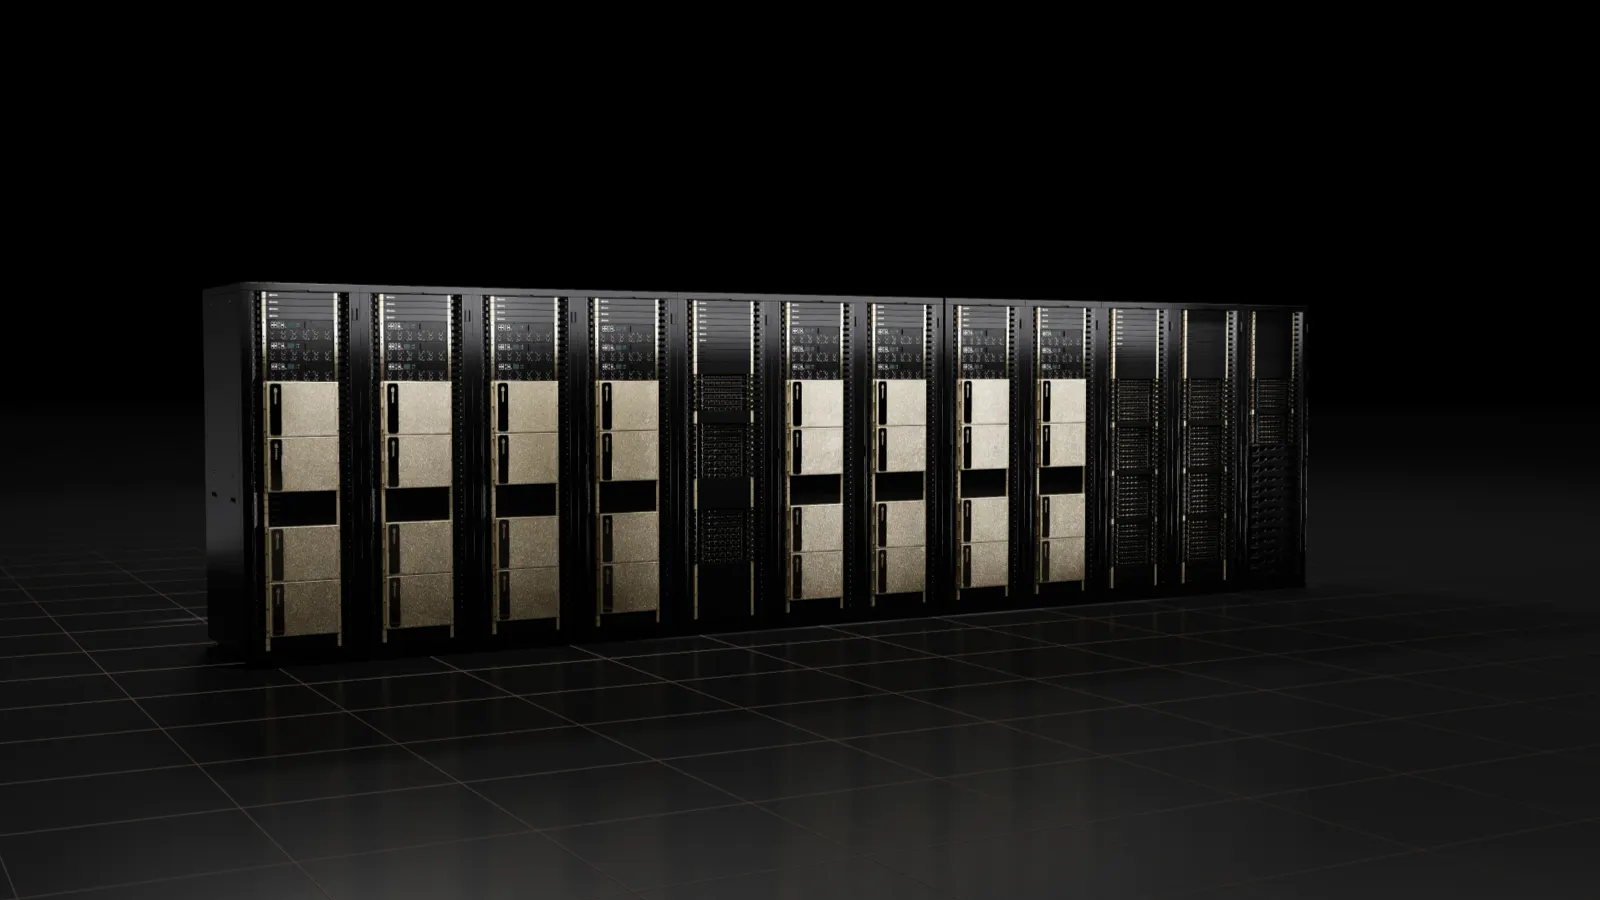 Containment row Image: NVIDIA
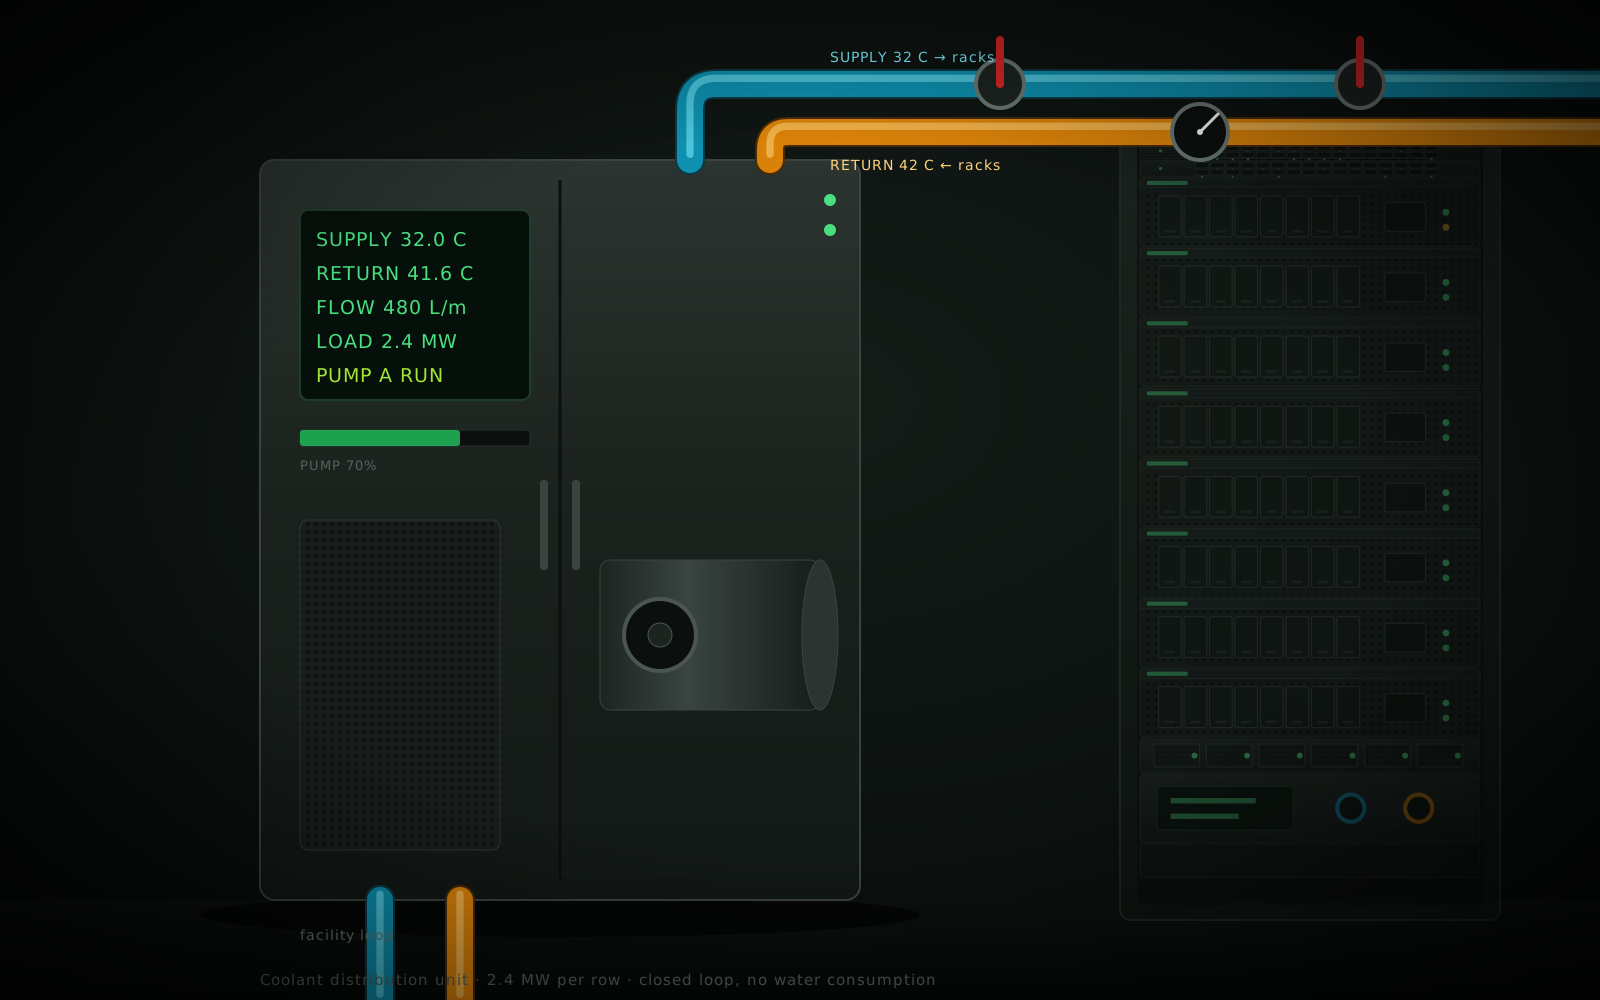 Cooling
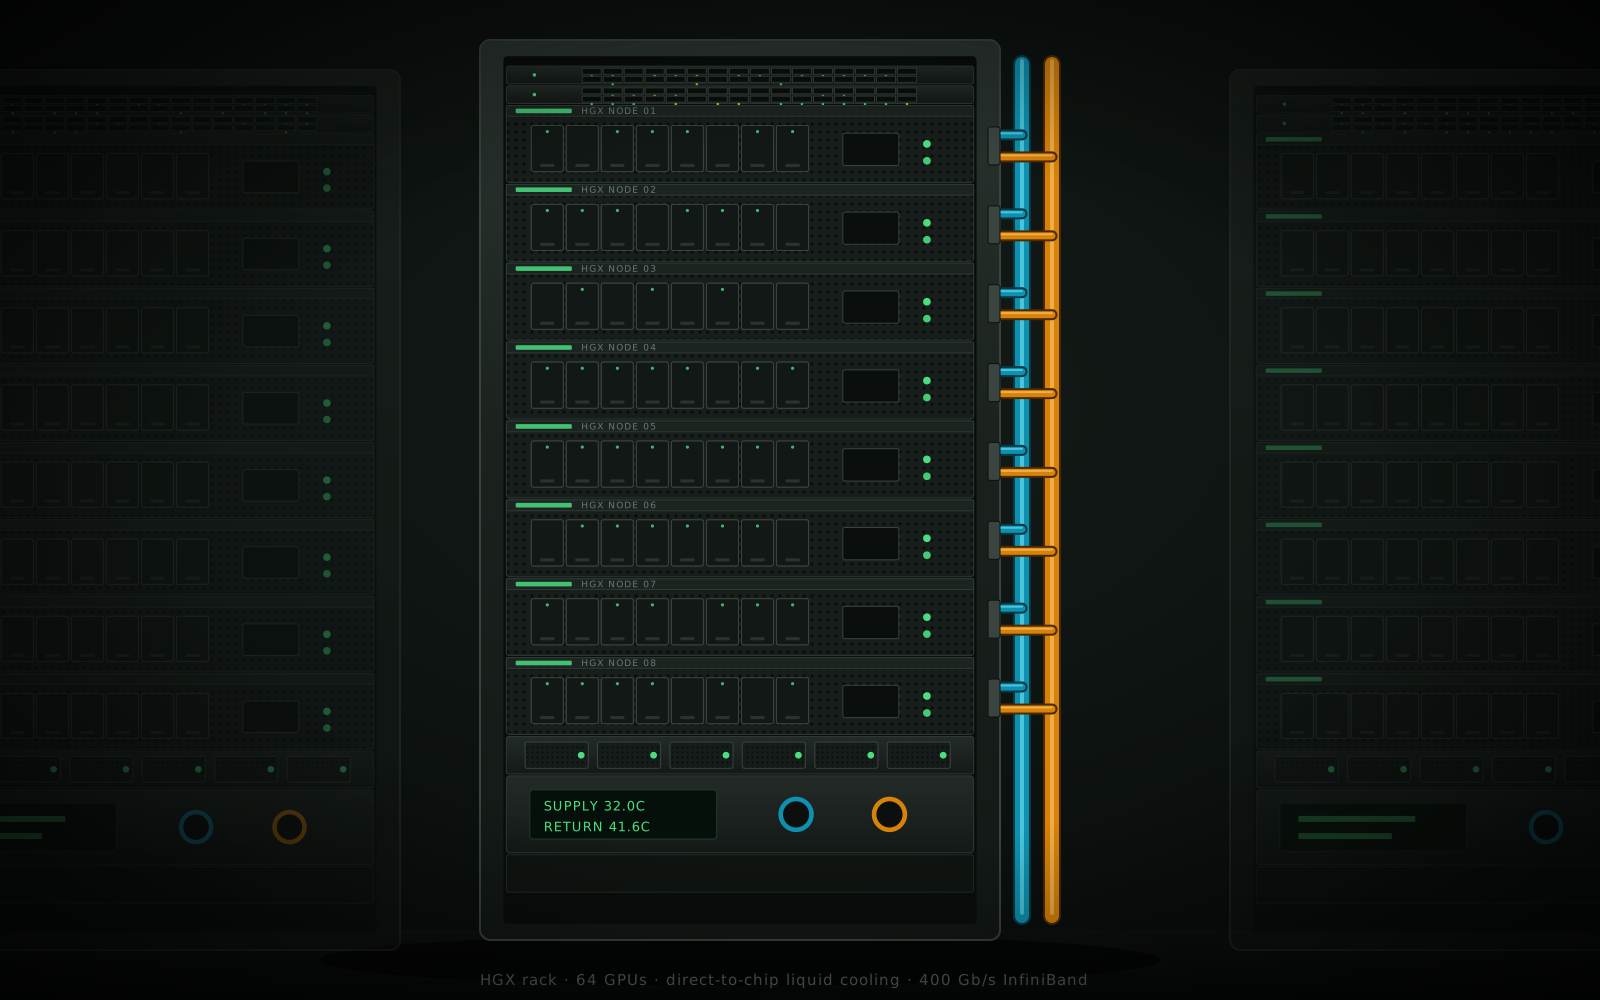 HGX rack
Your hardware, our halls
Custom cluster customers can deploy in a private cage in any region and get the same liquid cooling, renewable power and backbone we use for our own fleet, at our power purchase rate.
Custom Clusters- Rack densityUp to 130 kW liquid, 40 kW air
- Power pricingPass-through PPA rate
- Cross-connectsInfiniBand, 400G Ethernet, dark fiber
- Remote hands24/7, included in operations
- Minimum1 rack, 12-month term
See it for yourself
We host customer site visits in every region. Bring your infrastructure team and kick the tires.