Dedicated clusters, live in days
Production-ready NVIDIA HGX B200, H200 and H100 clusters from 16 to 1,024+ GPUs, interconnected with NVIDIA Quantum-2 InfiniBand and tuned for distributed training, fine-tuning and inference at scale.
2-week to multi-year terms. Managed Slurm or Kubernetes included.
Flat rates that fall as you scale
Flat per-GPU-hour pricing that includes InfiniBand, parallel storage, orchestration and support. Reserve for two weeks to a year on demand, or commit longer for the lowest rates.
NVIDIA HGX B200
- 16 GPUs $5.49 /GPU/hr
- 64 GPUs $5.09 /GPU/hr
- 256+ GPUs $4.79 /GPU/hr
- GPU B200 SXM6
- Memory 180 GB HBM3e
- Term 2 weeks to 1 year
NVIDIA Quantum-2 InfiniBand, 400 Gb/s per GPU, 3.2 Tb/s per node
Multi-year reserved from $3.89/GPU/hr
Reserve B200 capacityNVIDIA HGX H200
- 16 GPUs $3.89 /GPU/hr
- 64 GPUs $3.59 /GPU/hr
- 256+ GPUs $3.39 /GPU/hr
- GPU H200 SXM
- Memory 141 GB HBM3e
- Term 2 weeks to 1 year
NVIDIA Quantum-2 InfiniBand, 400 Gb/s per GPU, 3.2 Tb/s per node
Multi-year reserved from $2.69/GPU/hr
Reserve H200 capacityNVIDIA HGX H100
- 16 GPUs $2.59 /GPU/hr
- 64 GPUs $2.39 /GPU/hr
- 256+ GPUs $2.19 /GPU/hr
- GPU H100 SXM
- Memory 80 GB HBM3
- Term 2 weeks to 1 year
NVIDIA Quantum-2 InfiniBand, 400 Gb/s per GPU, 3.2 Tb/s per node
Multi-year reserved from $1.59/GPU/hr
Reserve H100 capacityAll cluster prices include NVIDIA Quantum-2 InfiniBand, 100 TB of parallel file storage per 16 GPUs, managed orchestration and 24/7 support. Additional parallel storage is priced per TB on request.
A fabric built for the GPU, not around it
Every HGX B200 node ships with eight ConnectX-7 adapters, one per GPU, into a rail-optimized non-blocking Quantum-2 fat tree. SHARP in-network reductions cut all-reduce time and free GPU cycles for math.
- Rail-optimized topology keeps GPU-to-GPU traffic on the shortest path
- SHARP v3 offloads collective operations into the switches
- GPUDirect RDMA and Storage move data without touching the CPU
- NCCL tuned by us with topology-aware configs shipped in every image
Measured bus bandwidth vs. theoretical at 256 GPUs, 8 GB messages.
Llama-style 70B, 16 to 256 GPUs, tokens per second per GPU.
Aggregate read from parallel filesystem at 512 GPUs.
Full 70B checkpoint to persistent storage, 128 GPUs.
What a reserved cluster is built from
Every cluster ships as complete racks: HGX nodes, top-of-rack InfiniBand, in-rack coolant distribution and parallel storage, burned in for 72 hours before handover.
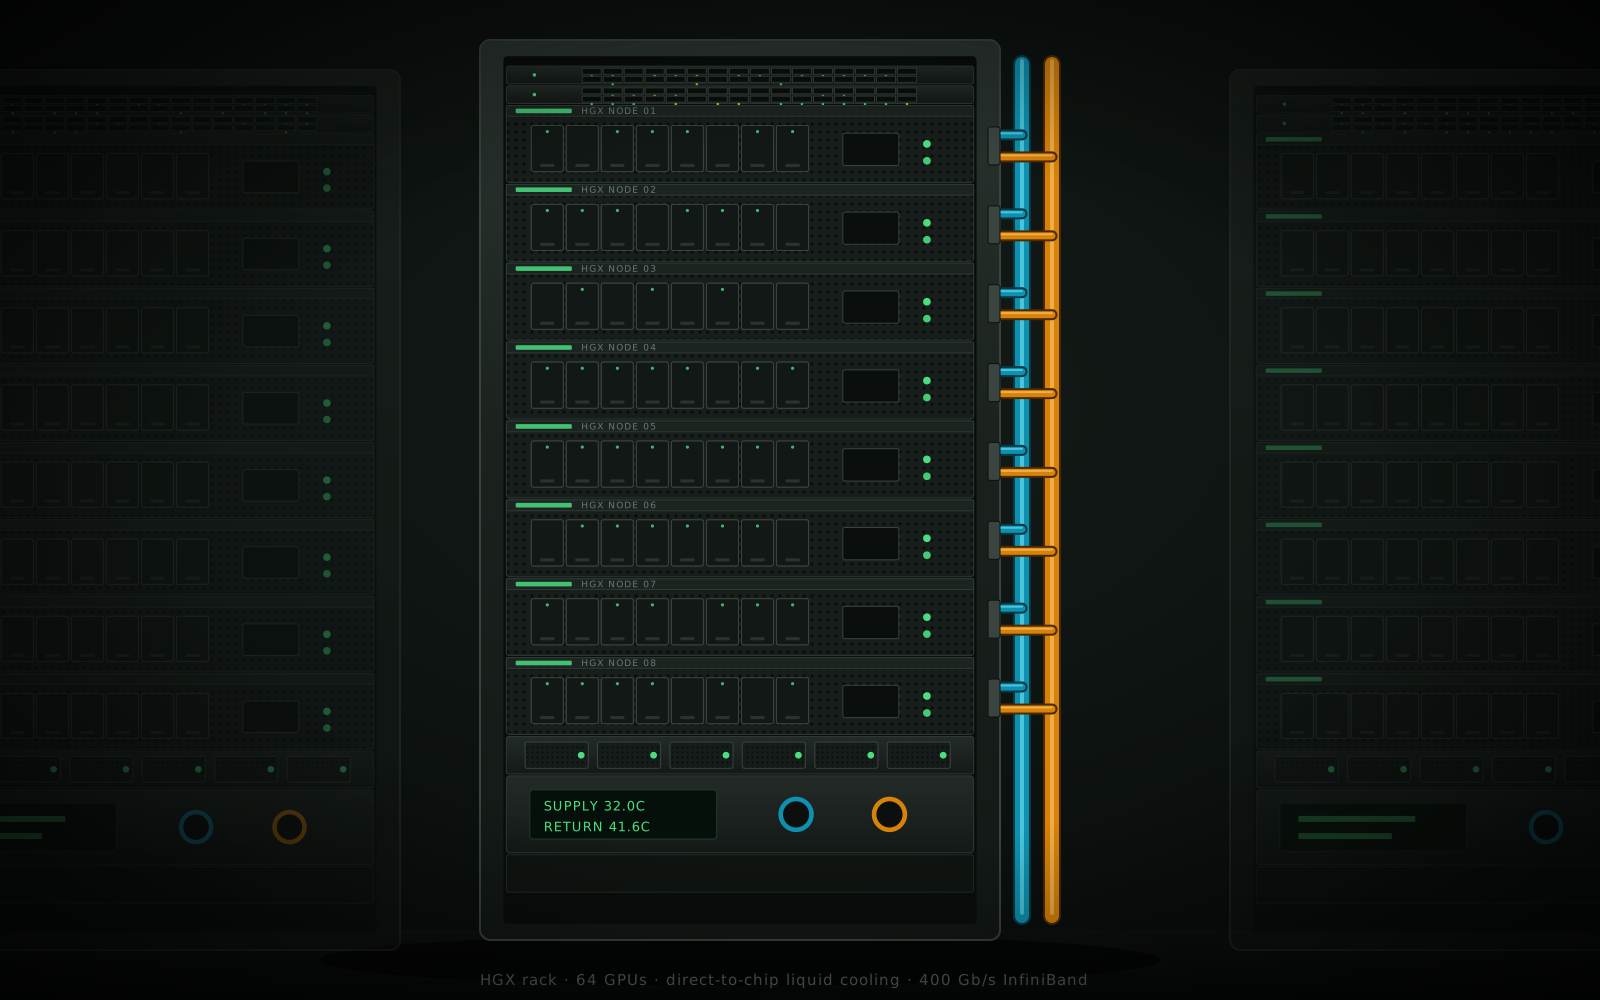 HGX rack
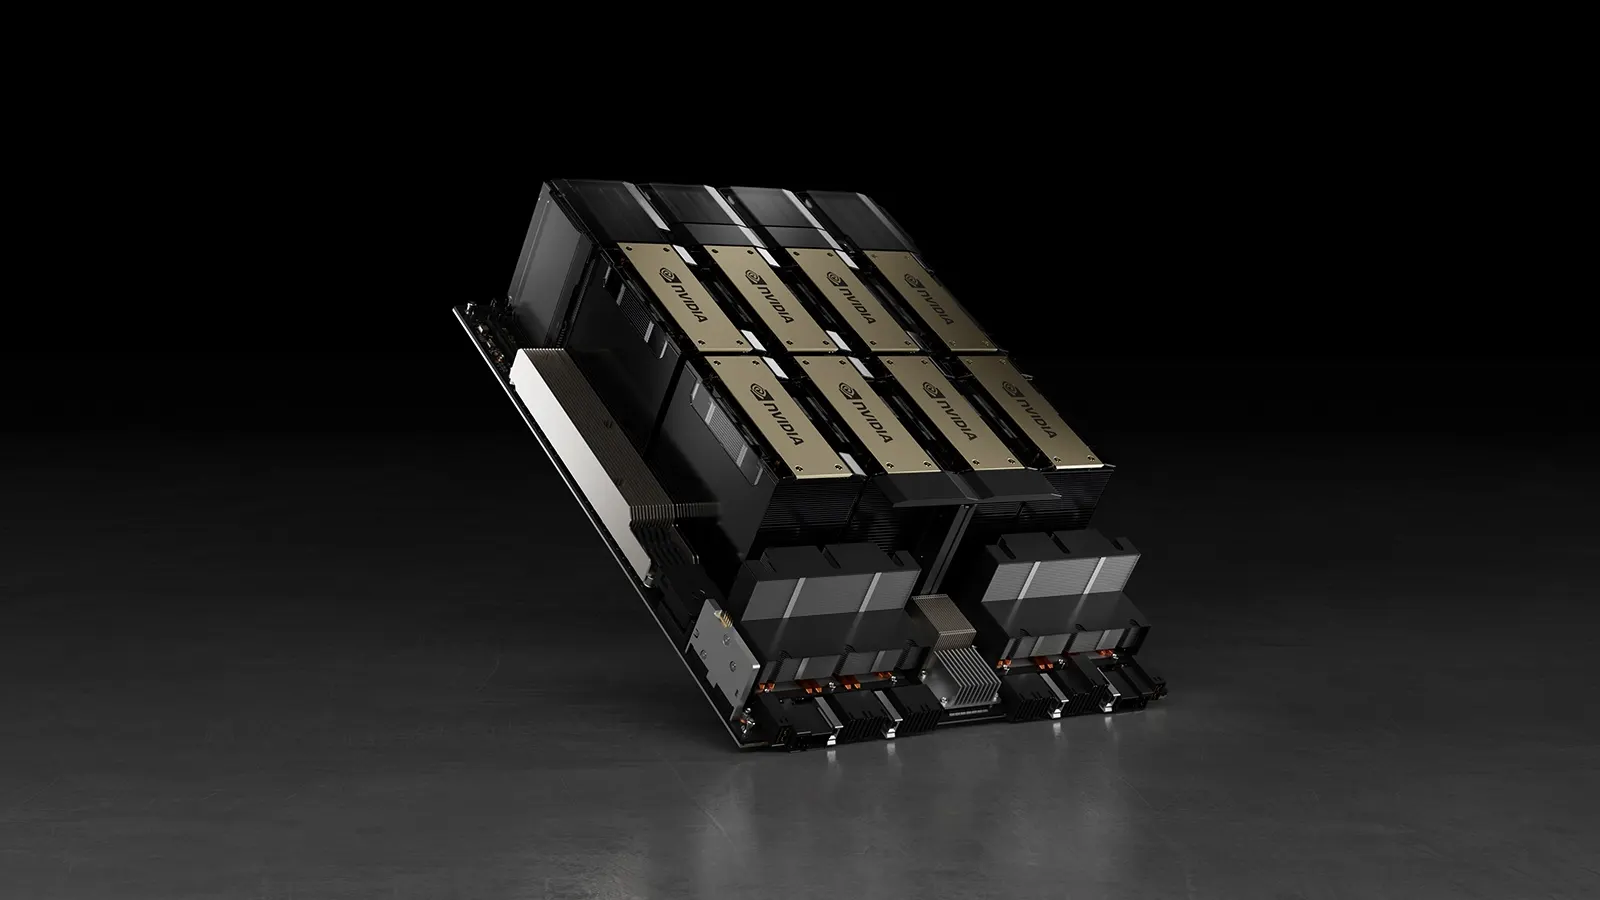 HGX node Image: NVIDIA
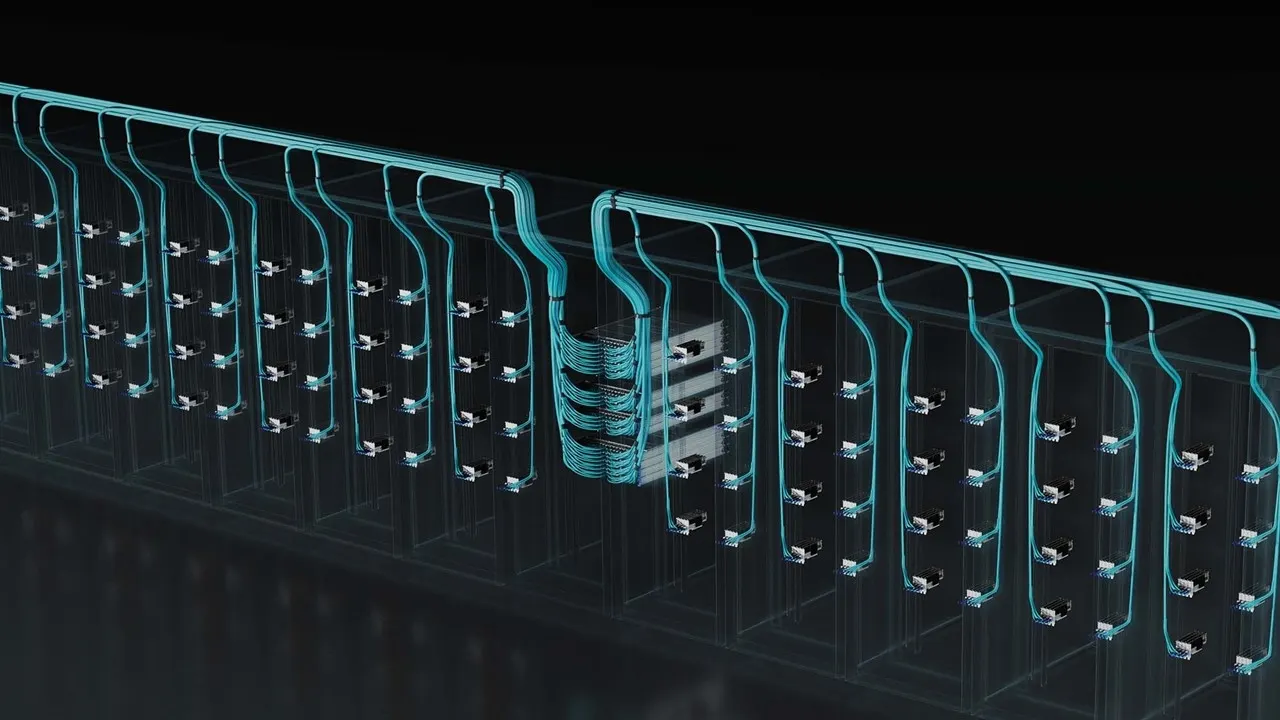 InfiniBand spine Image: NVIDIA
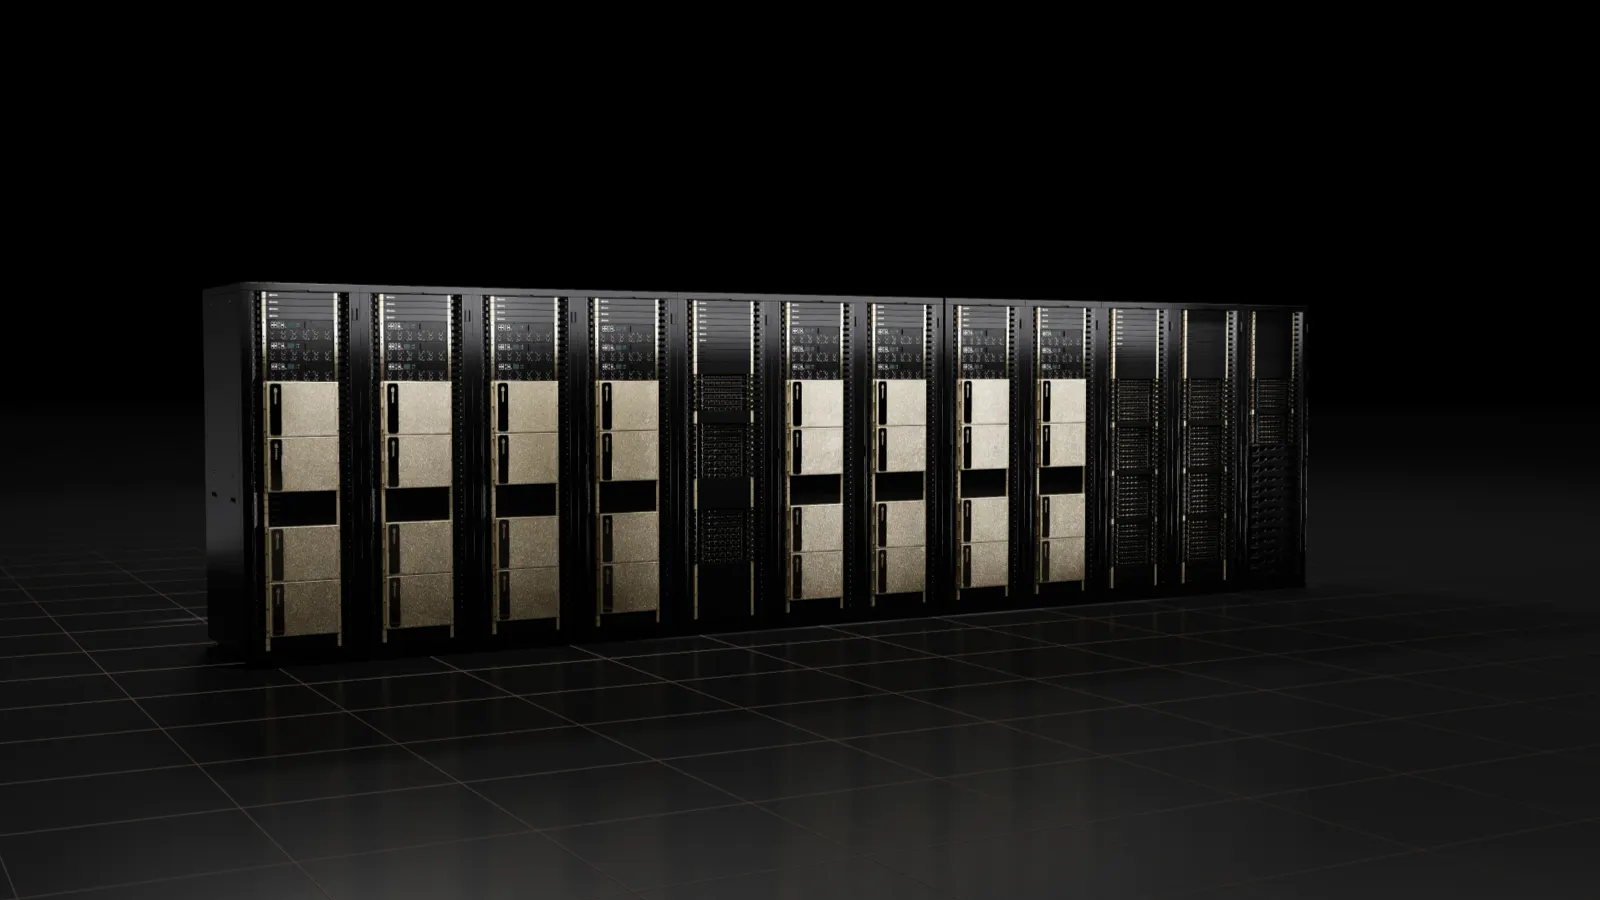 Containment row Image: NVIDIA
Everything a production cluster needs, included
Compliance built in
SOC 2 Type II and ISO 27001 environments, single-tenant fabric, encryption at rest and in transit. HIPAA-ready configurations on request.
Managed Slurm or Kubernetes
Job scheduling, GPU operators, network operators and monitoring pre-configured. Or take bare metal and run your own.
Parallel storage
High-performance file system with 1+ TB/s aggregate throughput, plus S3-compatible object storage with no transfer fees.
Self-service and observability
Provision, resize and monitor from the dashboard. Per-GPU metrics, fabric health and job telemetry, exportable to your stack.
From request to running jobs
A solutions engineer is assigned to every cluster and stays with you for the life of the contract.
- 01
Tell us what you need
GPU type, count, term, region and storage. We confirm capacity and send a quote the same day.
- 02
We provision and burn in
Nodes are imaged, the InfiniBand partition is configured and every GPU and link is stress-tested. You receive an acceptance report.
- 03
Onboarding session
We walk your team through the scheduler, storage, monitoring and NCCL settings tuned for your topology, and review your first job together.
- 04
Train, then grow
Add nodes into the same fabric, extend the term or migrate to a newer generation. Your data and images move with you.
Flat pricing, no surprise line items
| Component | Included | Optional add-ons |
|---|---|---|
| Compute | HGX B200 / H200 / H100 nodes, 8 GPUs each, dual CPUs, 1.8 to 2.9 TiB RAM, 22 TiB local NVMe | GB200 NVL72 racks, HGX B300 early access |
| Networking | Non-blocking Quantum-2 InfiniBand at 400 Gb/s per GPU, 200 Gb/s Ethernet, private VPC | Dedicated interconnect to your cloud or office, Quantum-X800 at 800 Gb/s |
| Storage | 100 TB parallel file storage per 16 GPUs, unlimited object storage at $0.02/GB-month | Additional parallel storage, cross-region replication |
| Orchestration | Managed Slurm or Kubernetes, GPU and Network Operators, container registry | Run:ai, custom scheduler integrations |
| Monitoring | Per-GPU metrics, fabric health, alerting, Prometheus and Grafana endpoints | Custom dashboards, integration with your observability stack |
| Support | 24/7 engineer on call, named solutions engineer, 99.9 percent SLA, hot spares | Embedded ML engineering via Managed Training |
Run on a reserved cluster today, take delivery of your own tomorrow
Many customers train on reserved capacity while we build their physical cluster. The stack is identical, so migration is a scheduler config change.
How quickly can a cluster be ready?
Clusters of 16 to 128 GPUs are typically live within 2 to 5 business days. Larger clusters depend on capacity in your preferred region; our median for 256 GPUs is 9 days. Contact us for current availability.
What is the minimum term?
Two weeks. Pricing improves at 3, 6 and 12 months, and multi-year reserved terms are available at the lowest rates. You can extend or grow a cluster at any point without migration.
Is the InfiniBand fabric shared with other customers?
No. Each cluster has its own dedicated non-blocking InfiniBand partition. Your nodes, switches and storage are single tenant for the life of your contract.
Which orchestrators do you support?
We deliver clusters with managed Slurm or Kubernetes (with the NVIDIA GPU Operator and Network Operator) pre-configured, or bare metal with SSH if you prefer to run your own scheduler. Run:ai and SkyPilot integrations are available.
What happens if a node fails?
Every cluster includes hot spares in the same fabric. Failed nodes are swapped automatically within minutes, and our SLA credits you for any time below 99.9 percent availability.
Can we bring our own storage or connect to our cloud?
Yes. Clusters support VPC peering, dedicated interconnects and site-to-site VPN. We can also mount your existing NFS or object storage, though in-region parallel storage is faster and included.
Reserve your cluster
Tell us your GPU count, term and region. We'll confirm capacity and send a quote the same business day.