GPU infrastructure for training and inference
Rent NVIDIA GPUs by the minute, reserve dedicated InfiniBand clusters, or have us design, build and operate a physical cluster to your spec. Then let our ML engineers train your models on it.
No minimums. Billed by the minute. B200, H200 and H100 available today.
One provider, from a single GPU to a sovereign AI factory
Most providers rent you compute. We also build it, own the power behind it, and staff the engineers who make it useful.
The latest GPUs, none of the setup
On-demand instances and reserved clusters with the latest NVIDIA Blackwell and Hopper GPUs, non-blocking InfiniBand and a software stack that works the moment you log in.
Explore GPU CloudOwn the hardware, skip the ops hiring
We design, procure, build and operate physical GPU clusters in your facility or ours. Single tenant, fully owned, with your security posture enforced at the hardware layer.
Build a custom clusterML engineers on your side of the table
Our ML engineers fine-tune, align, evaluate and deploy models on your behalf. You keep the weights, the code and the IP. We keep the pager.
See Managed TrainingFrom one GPU to thousands, on one stack
Start with one GPU. Grow to thousands. Same stack, same team, same dashboard.
GPU Cloud
1x to 8x NVIDIA GPU instances. Launch in under a minute, pay by the minute, scale with the API.
- B200, H200, H100, A100, L40S and more
- From $0.49 per GPU-hour
- Persistent storage and 10 TB of free egress a month
GPU Clusters
16 to 1,024+ GPUs on NVIDIA Quantum-2 InfiniBand with managed Slurm or Kubernetes. Live in days.
- HGX B200, H200 and H100 nodes
- From $2.19 per GPU-hour, $1.59 on multi-year terms
- 2-week to multi-year terms
Custom Clusters
Physical clusters designed and built to your requirements, on premises or colocated in our facilities.
- 8 to 4,096+ GPUs, liquid cooled
- Design, procurement, build, operations
- Delivered in 4 to 24 weeks
Don't have an ML team? Borrow ours.
From a four-week fine-tuning sprint to multi-month foundation model pre-training, our engineers run the whole pipeline: data, training, evaluation and deployment. You own everything we produce.
NVIDIA HGX systems on the fleet today
Each is a full NVIDIA HGX baseboard with NVLink and NVSwitch. In GPU Clusters and custom builds they run in liquid-cooled racks with 400 or 800 Gb/s InfiniBand.
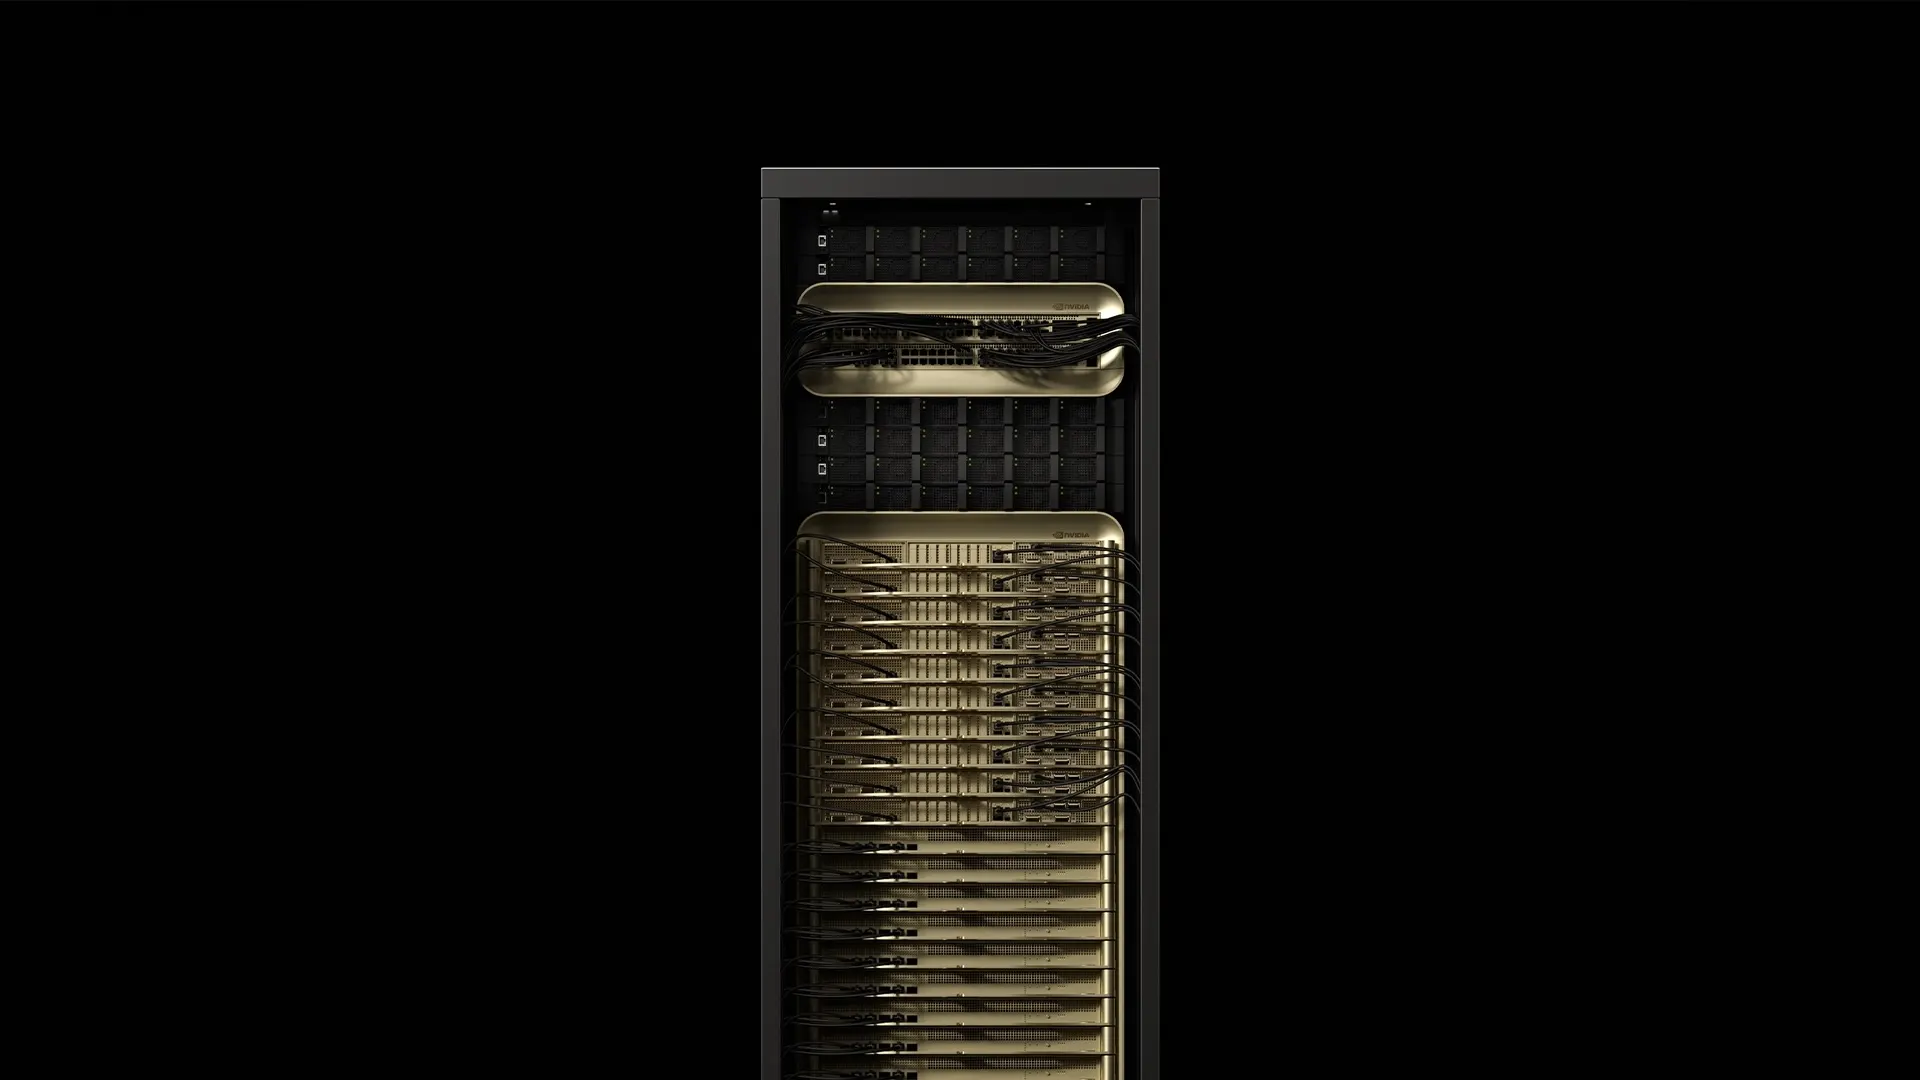 Image: NVIDIA
NVIDIA HGX B300
The largest memory per GPU available for trillion-parameter inference and reasoning-model training.
- GPUs 8x B300 SXM
- GPU memory 2.3 TB HBM3e
- NVLink 1.8 TB/s per GPU
- Fabric Quantum-X800 InfiniBand, 800 Gb/s
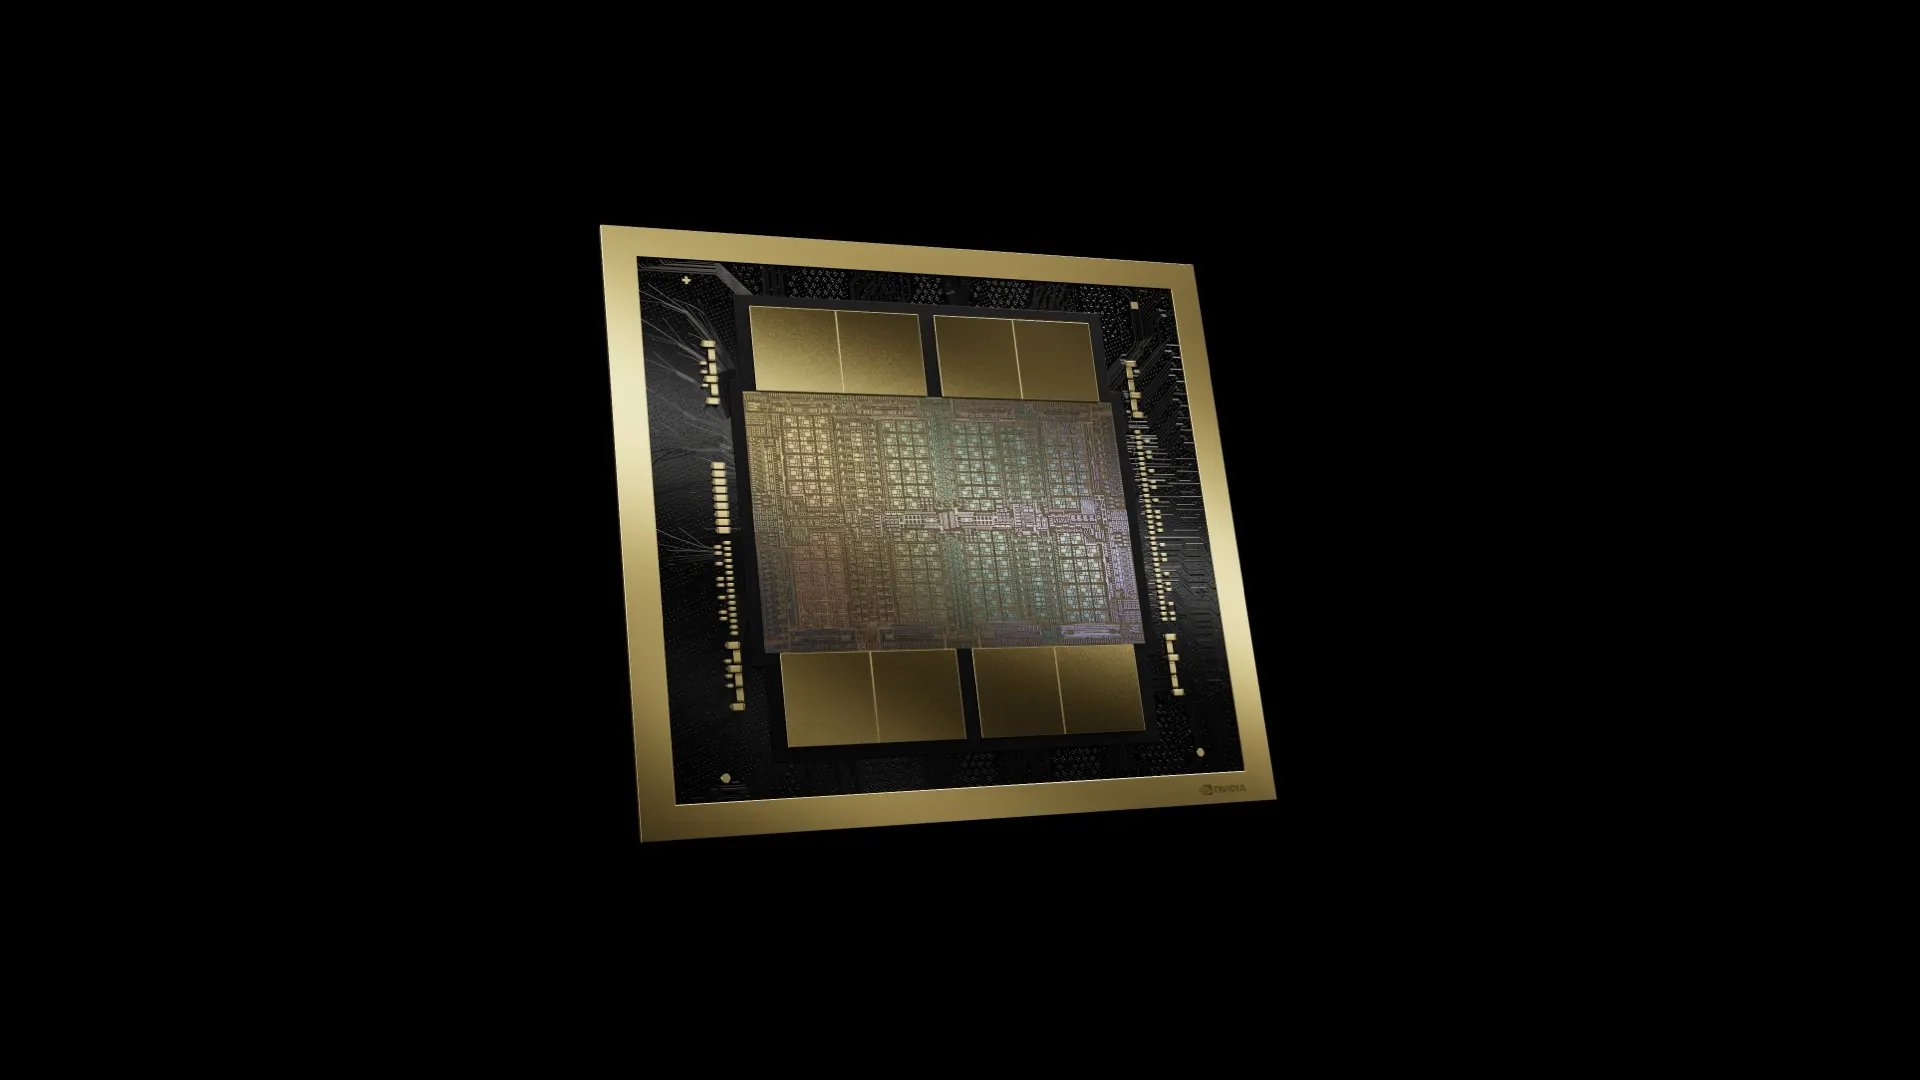 Image: NVIDIA
NVIDIA HGX B200
Up to 3x the training throughput of H100 for large language and multimodal models.
- GPUs 8x B200 SXM6
- GPU memory 1.4 TB HBM3e
- NVLink 1.8 TB/s per GPU
- Fabric Quantum-2 InfiniBand, 400 Gb/s
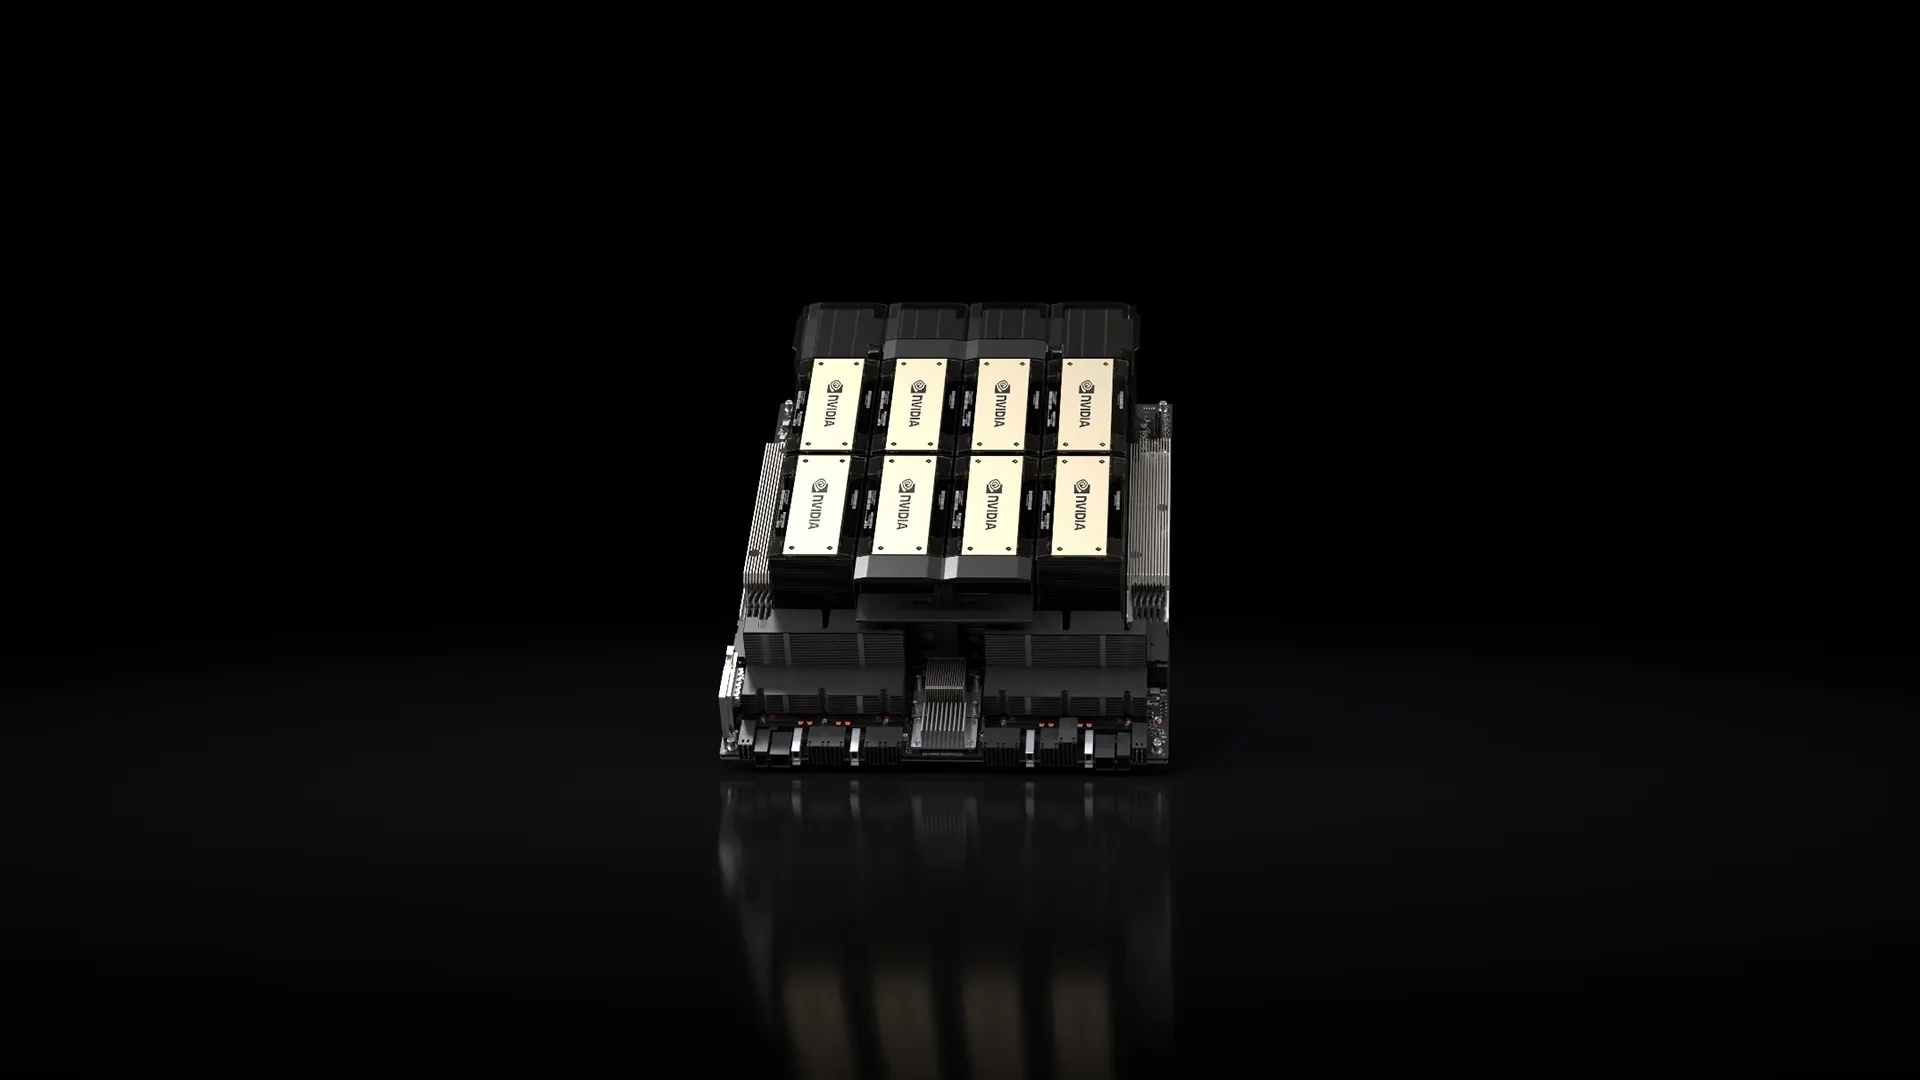 Image: NVIDIA
NVIDIA HGX H200
Hopper with 141 GB of HBM3e per GPU. The best price-to-memory ratio for inference at scale.
- GPUs 8x H200 SXM
- GPU memory 1.1 TB HBM3e
- Memory bandwidth 4.8 TB/s per GPU
- Fabric Quantum-2 InfiniBand, 400 Gb/s
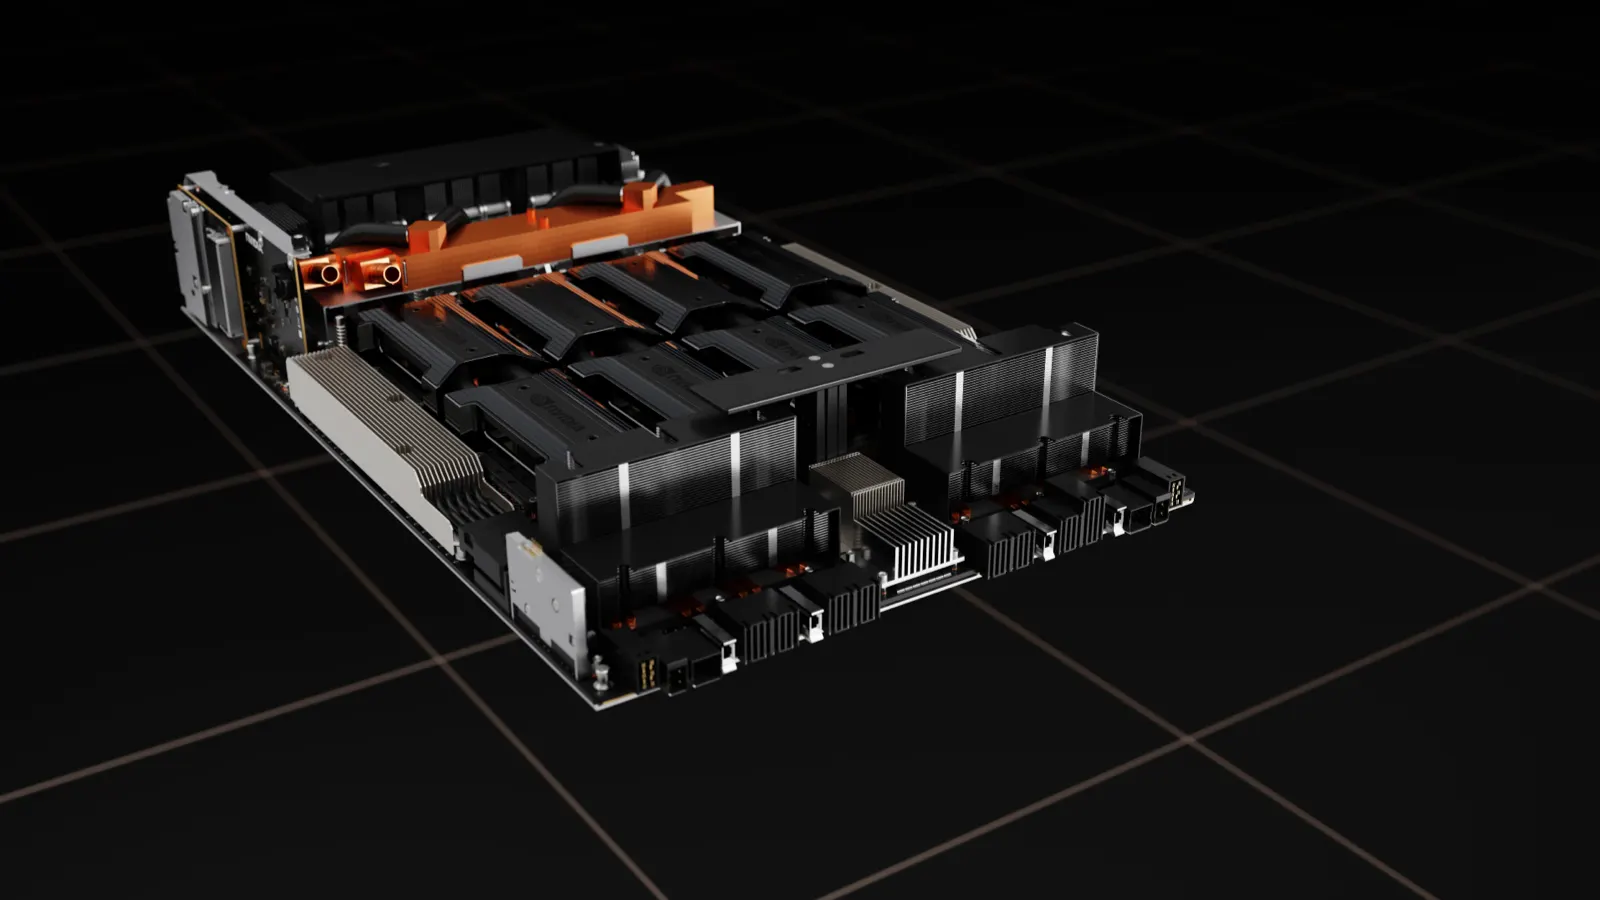 Image: NVIDIA
NVIDIA HGX H100
The proven workhorse for training and fine-tuning, now at its lowest price point ever.
- GPUs 8x H100 SXM
- GPU memory 640 GB HBM3
- Memory bandwidth 3.35 TB/s per GPU
- Fabric Quantum-2 InfiniBand, 400 Gb/s
See what your GPU-hour runs on
Liquid-cooled HGX racks, non-blocking InfiniBand and row-level cooling, in halls built from the slab up for 130 kW racks.
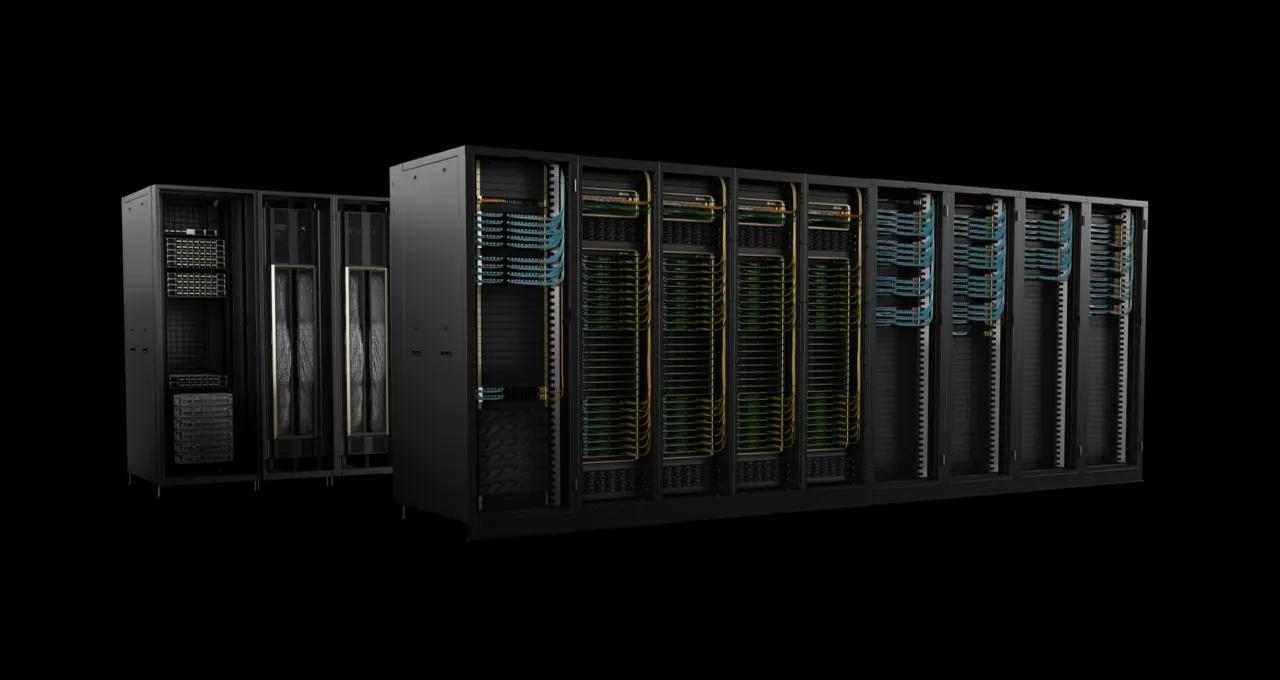 Data hall Image: NVIDIA
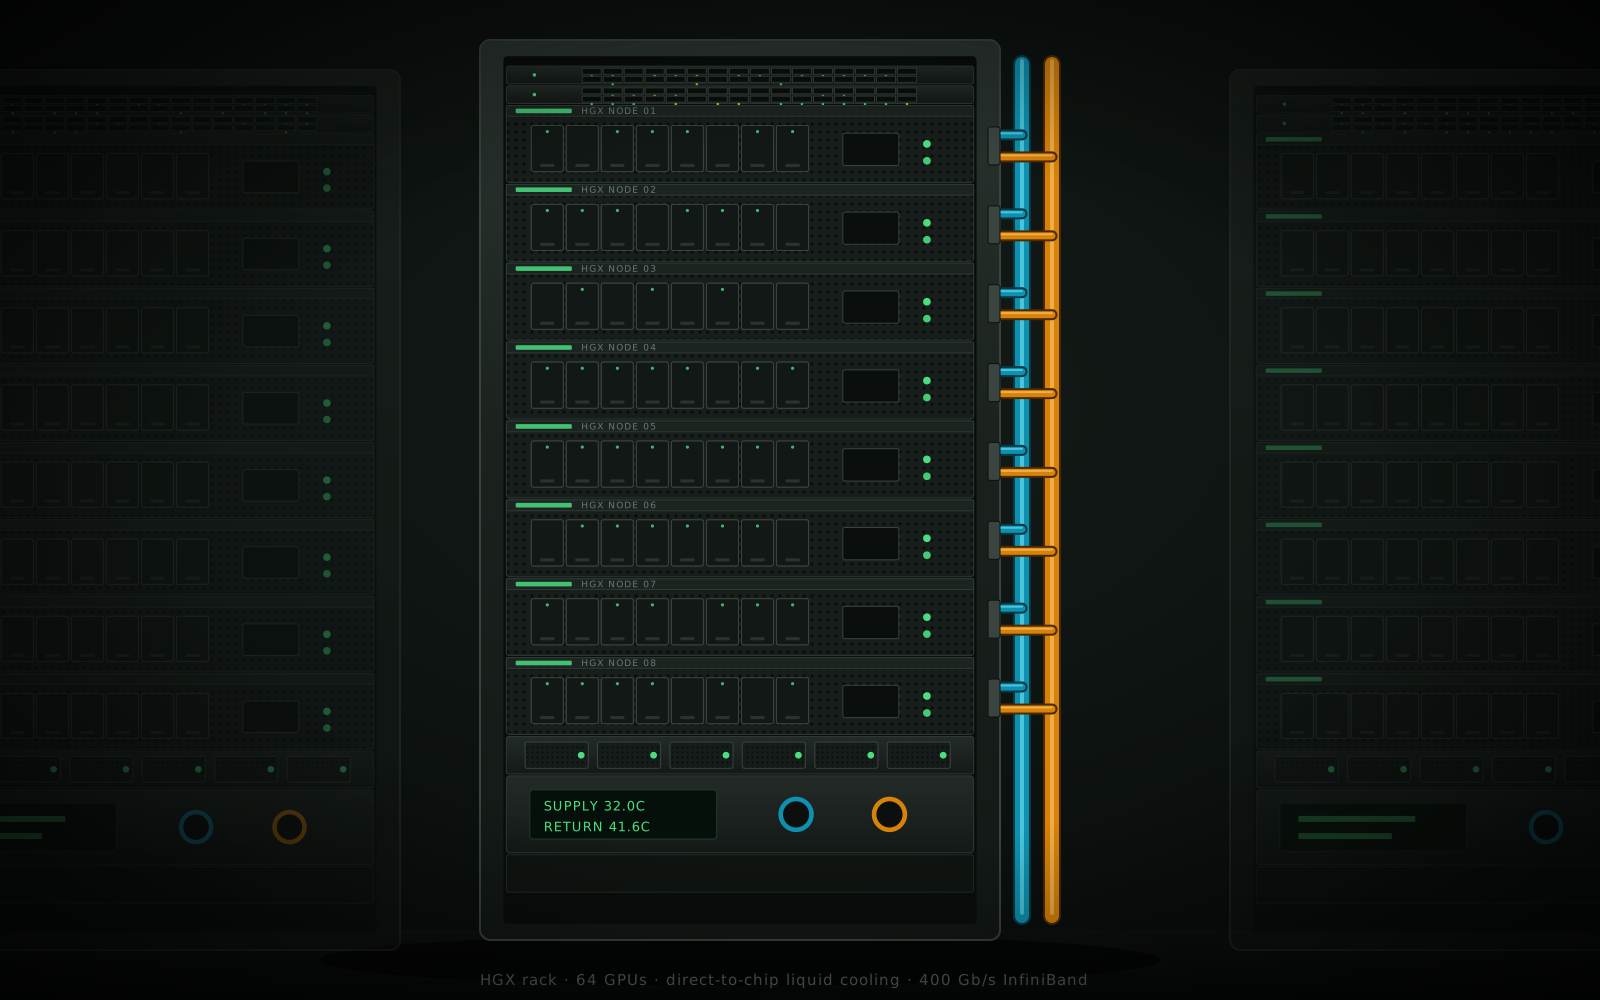 HGX rack
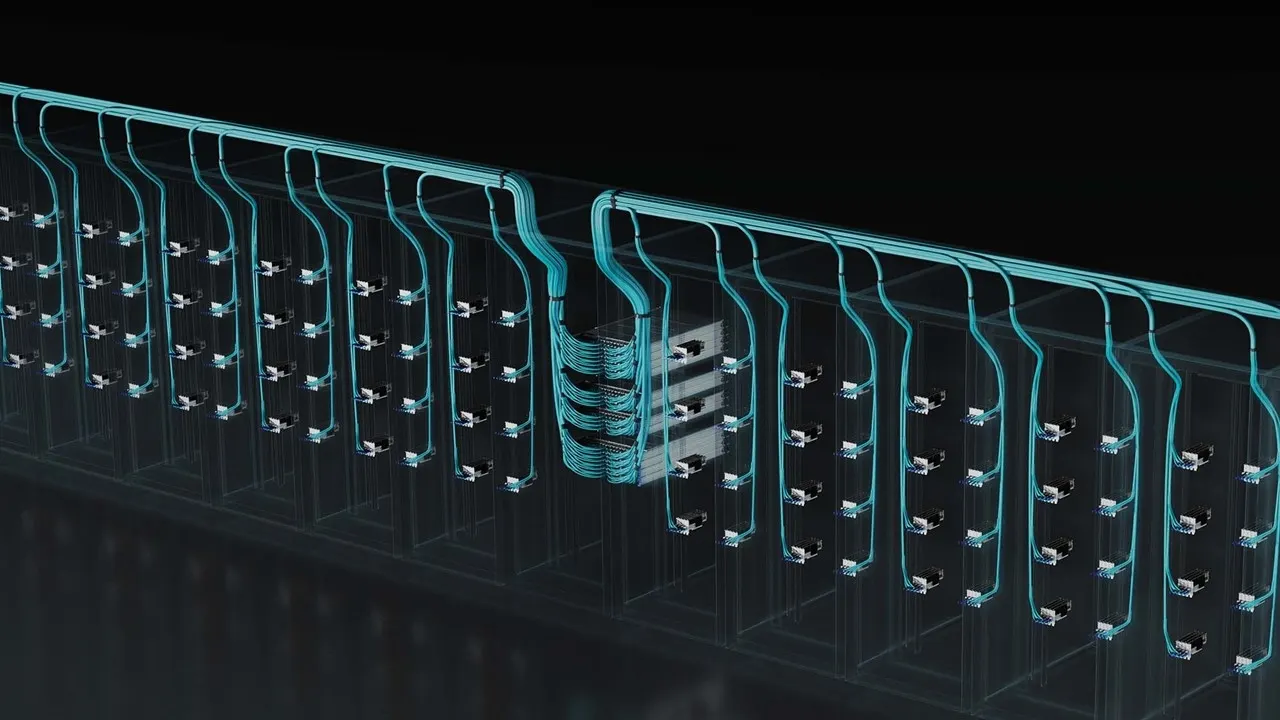 InfiniBand spine Image: NVIDIA
Powered by renewables. Cooled by liquid. Priced accordingly.
Our data centers sit next to hydro and wind generation and run direct-to-chip liquid cooling. That gives us a PUE of 1.1, a carbon intensity below 15 g CO2e per kWh, and power costs low enough to pass on.
Your own nodes, your own fabric, your own keys
Every cluster and every reserved node is dedicated to one customer. No shared GPUs, no noisy neighbors, no surprises in an audit.
- SOC 2 Type II and ISO 27001 certified, with reports available under NDA
- Encrypted at rest and in transit, with an isolated InfiniBand partition per cluster
- Your keys, your VPC: bring your own KMS and peer into private networks
- Data residency guaranteed per region, with hardware you can visit
Transparent, per-minute pricing
No reservations required to get these rates. Reserved clusters and multi-year terms go lower.
Build on GREENAIBOX
Launch an instance in minutes, reserve a cluster in days, or talk to us about building your own.