Your AI factory, built to spec
We design, procure, build and operate physical GPU clusters from 8 to 4,096+ GPUs, on your premises or colocated in our renewable-powered data centers. You own the hardware. We make it run.
Free architecture consultation. Transparent bill of materials. Delivered in 4 to 24 weeks.
Where your cluster lives is up to you
On-premises
We build inside your data center or server room. Includes site survey, power and cooling design, and any facility upgrades, managed end to end with your team.
Colocated at GREENAIBOX
Your hardware in our liquid-cooled, renewable-powered halls. Dedicated cage, private interconnect to your network, and power priced at our PPA rate.
Hybrid
Own a base cluster and burst to reserved GPU Clusters or on-demand instances on the same software stack, scheduler and storage namespace.
From a single HGX rack to NVL72 rows
Liquid-cooled HGX racks, NVL72-class rack-scale systems and the row-level cooling that keeps them at full clock, integrated and burned in before they reach your floor.
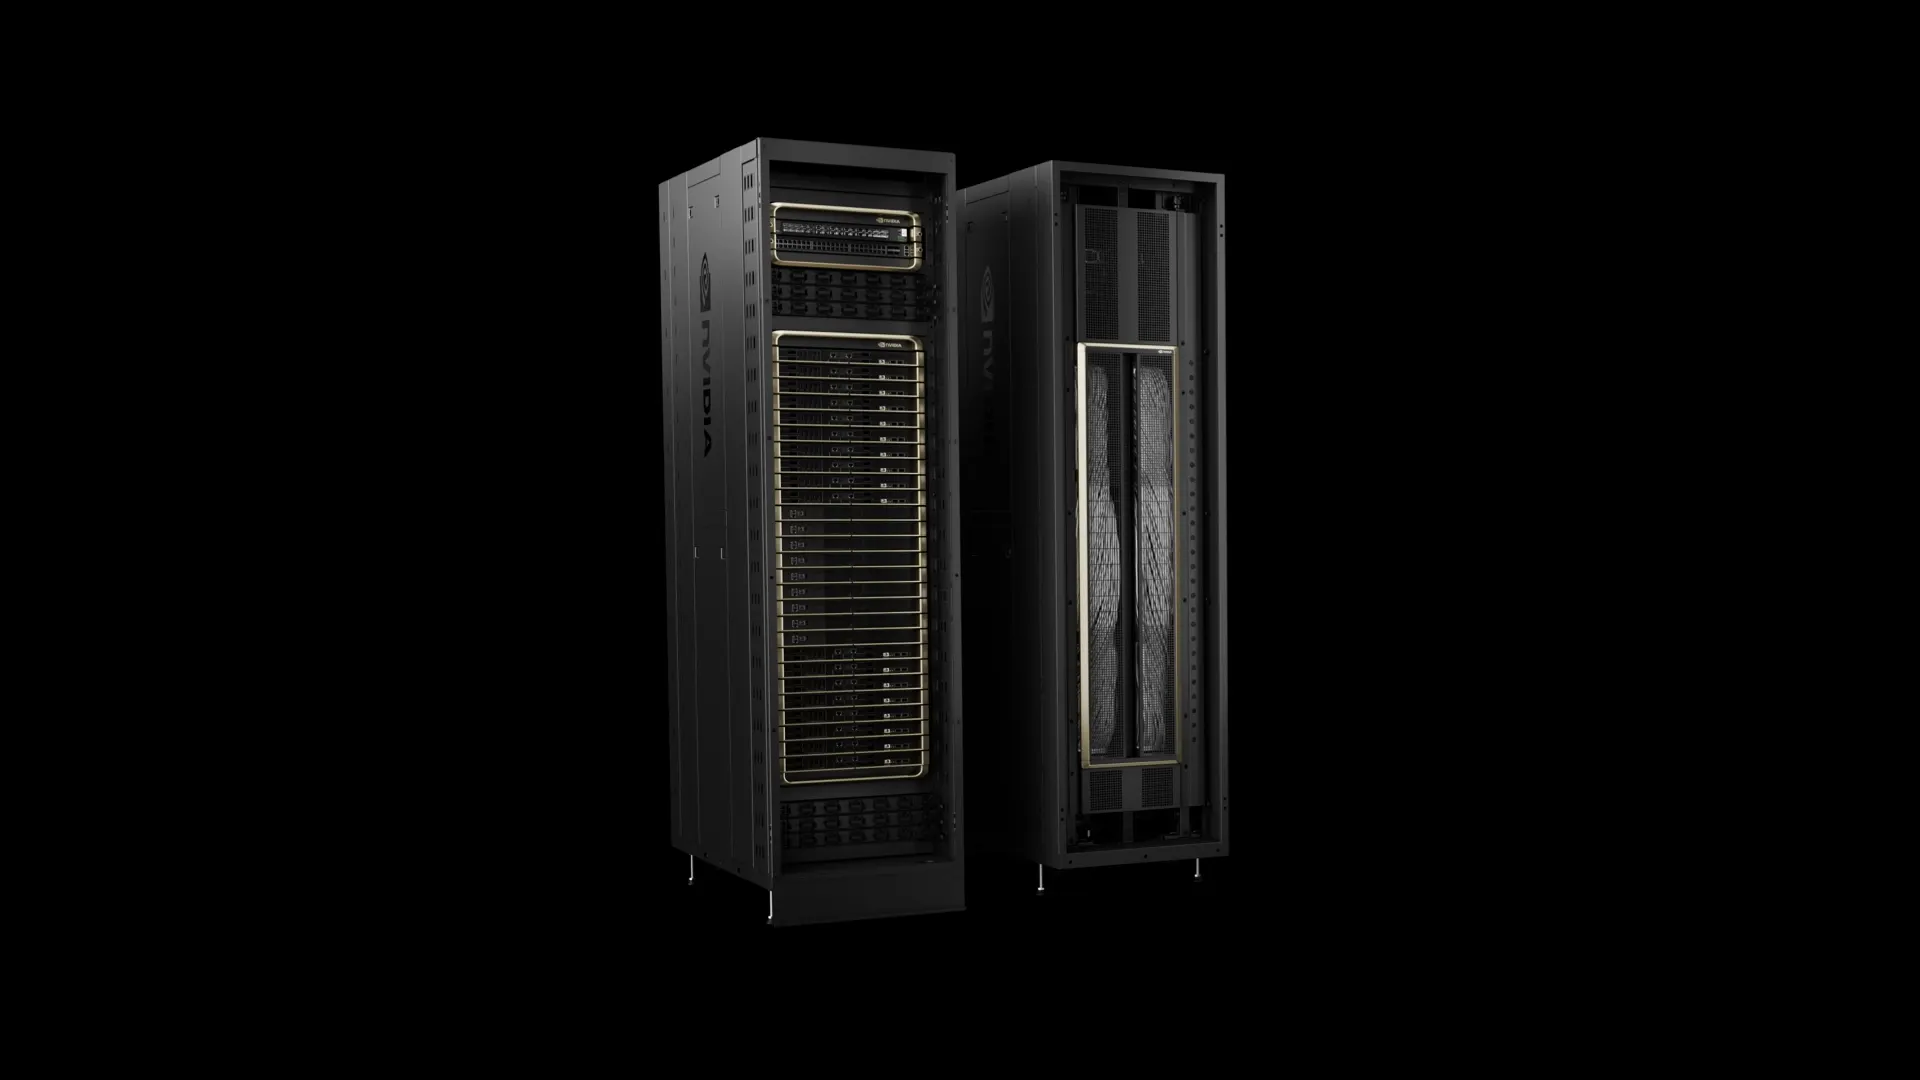 NVL72 rack Image: NVIDIA
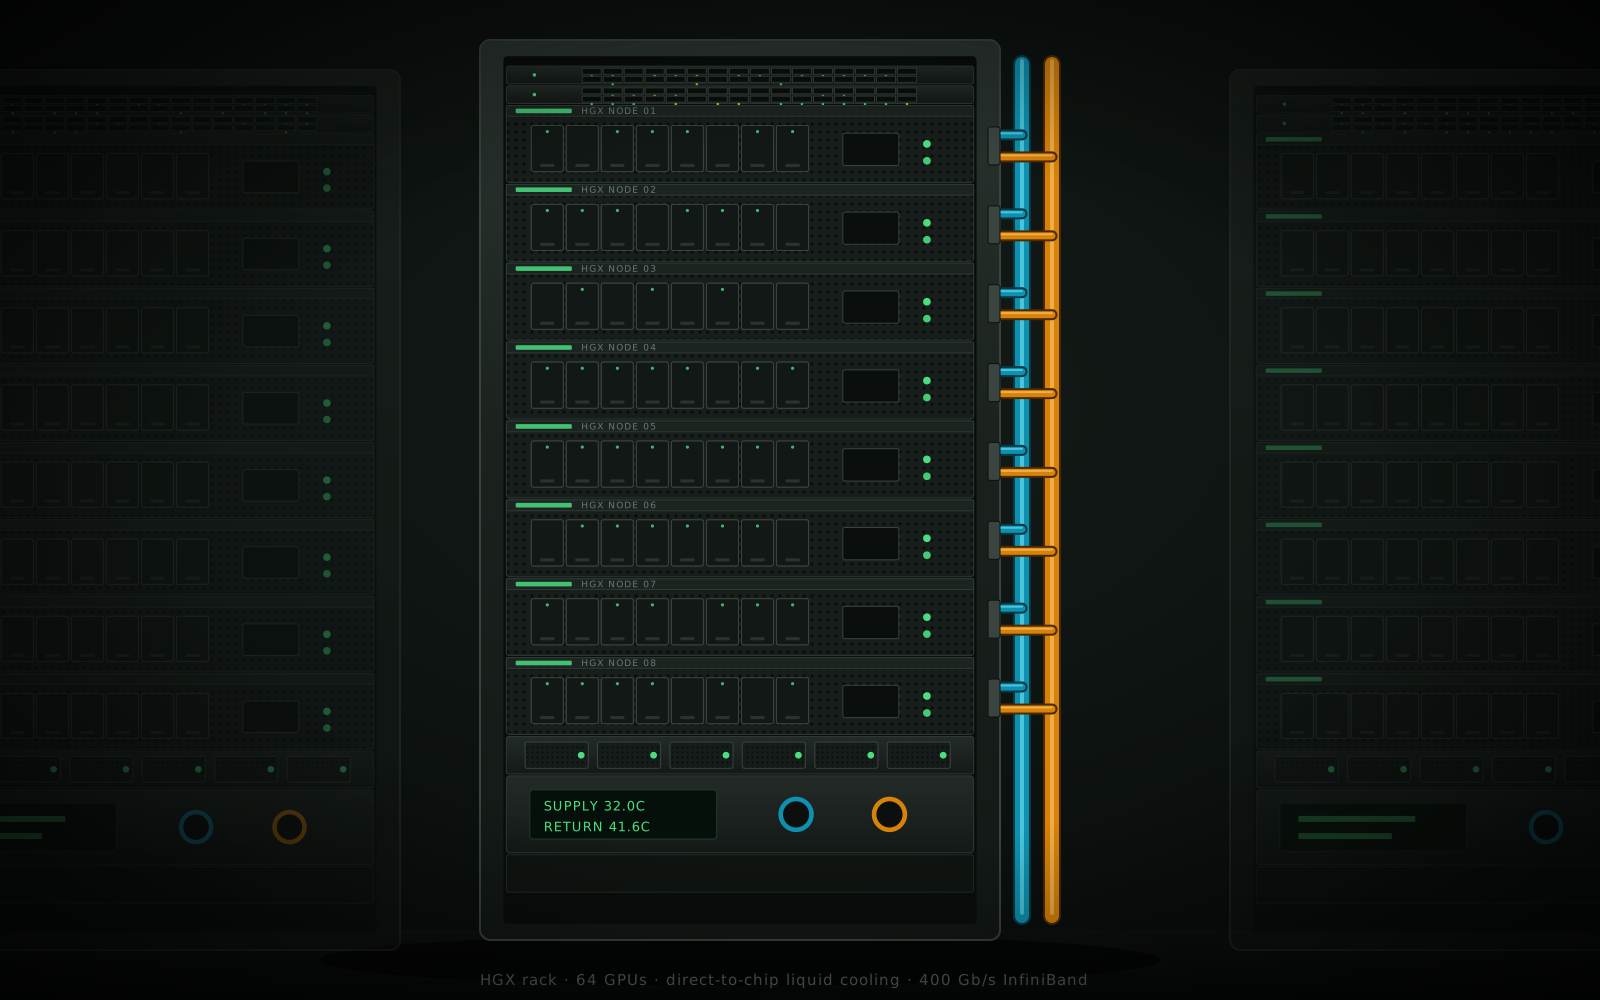 HGX rack
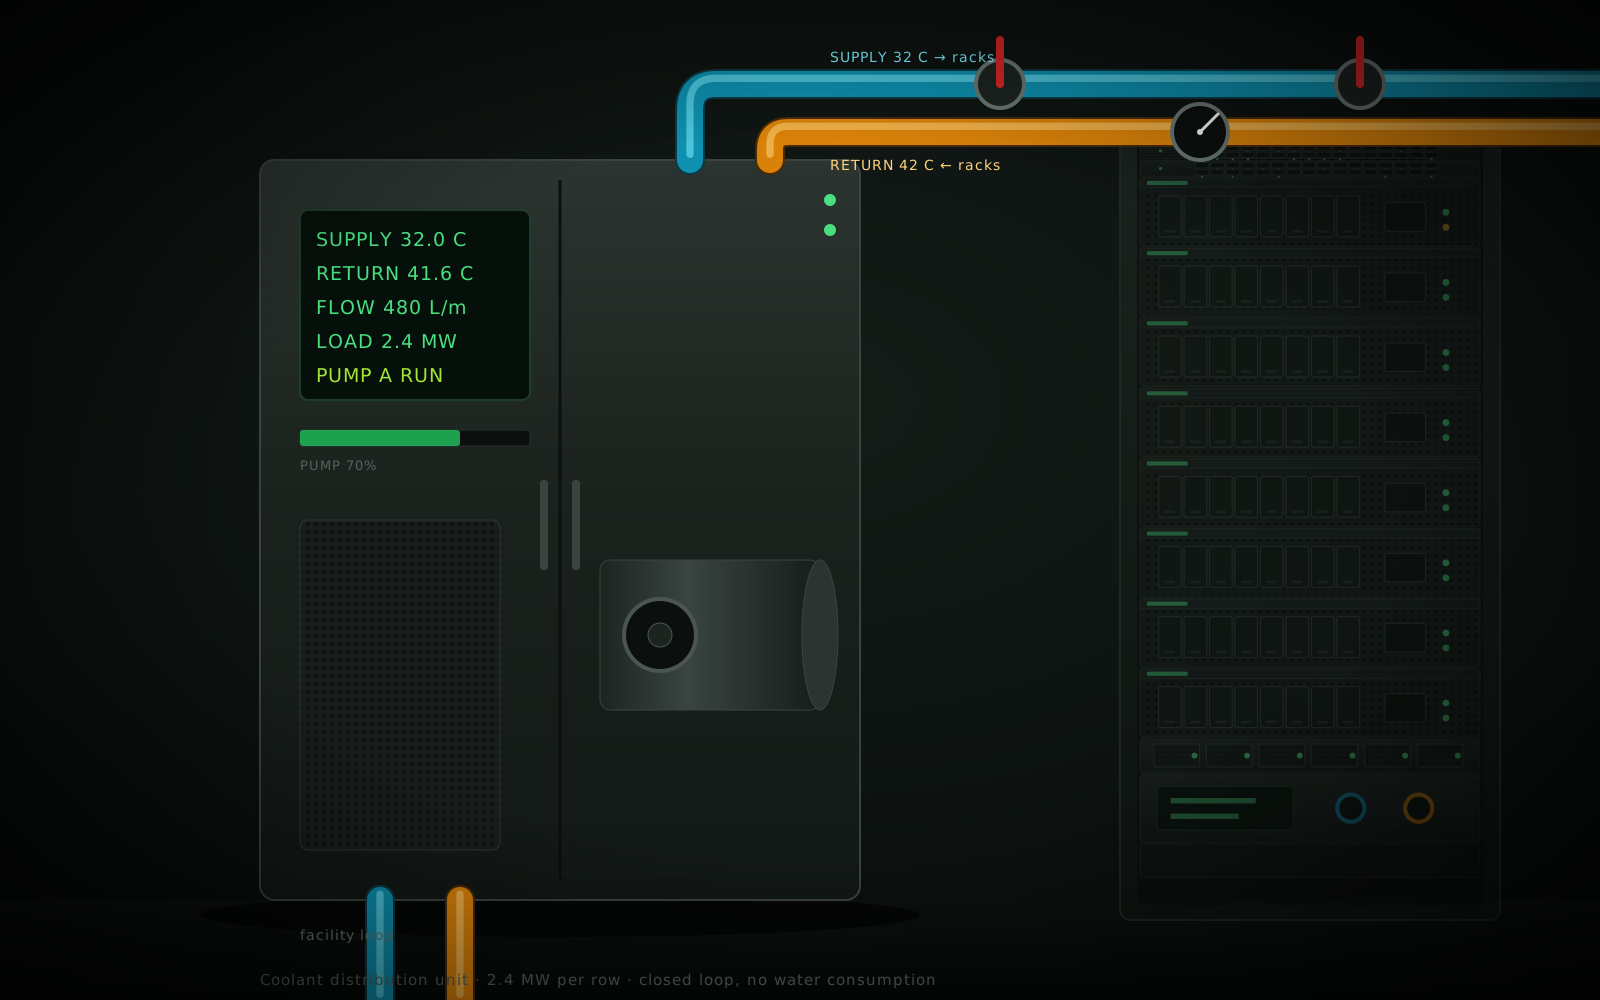 Cooling
Three starting points. Every build is bespoke.
Use these as a baseline for budgeting. Your design is sized to your workloads, facility and growth plan.
| Lab | Scale | Frontier | |
|---|---|---|---|
| GPUs | 8 to 32 GPUs | 64 to 256 GPUs | 512 to 4,096+ GPUs |
| Nodes | 1 to 4x HGX H200 or B200 nodes | 8 to 32x HGX B200 nodes | 64 to 512x HGX B200 / B300 or GB200 NVL72 racks |
| Fabric | 400 Gb/s InfiniBand or 200 Gb/s RoCE | Non-blocking Quantum-2 InfiniBand fat tree | Rail-optimized Quantum-X800, 800 Gb/s |
| Storage | 100 to 500 TB all-NVMe | 1 to 5 PB parallel file system | 10+ PB, 1+ TB/s aggregate |
| Power | 15 to 60 kW | 120 to 480 kW | 1 to 10 MW |
| Cooling | Air or rear-door heat exchanger | Direct-to-chip liquid cooling | Liquid cooling with facility water loop |
| Lead time | 4 to 6 weeks | 8 to 12 weeks | 12 to 24 weeks |
| Best for | University labs, R&D teams, fine-tuning and inference | Model companies, enterprise AI platforms, multi-team clusters | Foundation model pre-training, sovereign AI, national labs |
| Design a Lab cluster | Design a Scale cluster | Design a Frontier cluster |
From whiteboard to first training step
One team owns the whole project. No hand-offs between an integrator, a network vendor and a facilities contractor.
Start with a consultation- 01
Discovery and workload profiling
We profile your models, data and growth plans, and survey your facility or select a colocation site. Output: requirements document and budget range.
- 02
Architecture design
Compute, fabric topology, storage tiers, power, cooling and software stack, with a transparent bill of materials and total cost of ownership model.
- 03
Procurement
GPU allocation secured through authorized distribution at pass-through pricing. We manage vendors, logistics and warranty registration.
- 04
Build and burn-in
Rack, cable, image and validate every node and link in our integration facility. 72-hour burn-in under real distributed training workloads.
- 05
Deployment and acceptance
Installation on site, fabric bring-up, storage and scheduler configuration, then an acceptance test against agreed benchmarks.
- 06
Operations and lifecycle
24/7 monitoring, hardware replacement, firmware and software updates, capacity planning and quarterly reviews.
Best-of-breed, vendor-neutral
We design for your workload, not for a vendor's quota.
Compute
- NVIDIA HGX B300, B200, H200, H100
- NVIDIA GB200 / GB300 NVL72 racks
- AMD Instinct MI350 on request
- CPU nodes for data processing
Networking
- NVIDIA Quantum-2 and Quantum-X800 InfiniBand
- NVIDIA Spectrum-X Ethernet
- Rail-optimized, non-blocking topologies
- Out-of-band management fabric
Storage
- WEKA, VAST Data, DDN and Lustre
- All-NVMe scratch tiers
- S3-compatible object storage
- Backup and cross-site replication
Cooling
- Direct-to-chip liquid cooling
- Rear-door heat exchangers
- Immersion for dense deployments
- CDU and facility loop integration
Power
- Busway and PDU design to 130 kW per rack
- UPS and generator sizing
- Renewable PPA sourcing
- Metering and carbon reporting
Software
- GreenAI Stack images
- Slurm, Kubernetes, Run:ai
- Monitoring, alerting and logging
- Identity, secrets and policy
Infrastructure people who also run infrastructure
Transparent pricing
Hardware at pass-through cost with the full bill of materials on the table. Our fee is for design, integration and operations, not markup.
Supply you can count on
Allocation for NVIDIA HGX and NVL72 systems is reserved at contract signing so your timeline doesn't slip.
Operated by the team that built it
The engineers who designed your cluster run it. Same runbooks, monitoring and software we use on our own fleet.
Flexible financing
Purchase outright, lease over 3 to 5 years, or structure as a managed service with a monthly fee. We work with your finance team.
Who owns the hardware?
You do. We procure on your behalf with a transparent bill of materials and pass-through pricing, or you can purchase directly from our partners and have us integrate. Lease and financing options are available if you prefer to keep it off the balance sheet.
Can you build in our own data center?
Yes. We survey your facility for power, cooling and floor loading, design to what is available, and manage any upgrades with your facilities team. If your site cannot support the density, we colocate the cluster in one of our facilities and connect it privately to your network.
How long does a build take?
Lab-scale clusters (8 to 32 GPUs) take 4 to 6 weeks. Clusters of 64 to 256 GPUs take 8 to 12 weeks. Frontier-scale deployments take 12 to 24 weeks, driven mostly by GPU allocation and facility readiness. We reserve GPU supply at contract signing.
What does ongoing operations include?
24/7 monitoring, hardware replacement under warranty, firmware and driver lifecycle, scheduler and storage administration, security patching, capacity reporting and a named engineer. Operations contracts run 1 to 5 years and are priced per GPU per month.
What if we outgrow the cluster?
Every design leaves room in the fabric, power and storage for at least 2x growth. Adding nodes is a procurement and rack-and-stack exercise, not a redesign. We can also bridge with reserved GPU Clusters while new hardware ships.
Do you provide the ML engineers as well?
Yes. Managed Training can run on your cluster, so you can have us build the infrastructure and train the models on it while your team ramps up.
Get a cluster design in two weeks
Share your workloads, timeline and site. We'll return an architecture, a bill of materials and a total cost of ownership model, free of charge.